Why Our Workflows Keep Getting Better
Across this series, we've shown you a lot of what the inVibe Agent can do: run expert-engineered skills on voice data, prove itself against expert analysis before it ships, and answer your questions throughout the partnership.
Let's close with something true of every workflow we create. They all keep getting better. And the reason they do is the same reason you can trust them in the first place: our team of language experts.
Our Experts Notice What to Sharpen
Plenty of AI products talk about continuous improvement, and usually they mean a new model, a longer prompt, or a feature release (none of which necessarily produces better research outputs). Our Agent works differently because our process is different. Our improvement begins with something an expert can actually observe in the work.
When our language experts evaluate how a workflow handled a piece of analysis, they notice the things trained researchers are tuned to notice. Maybe a consequential concern raised by only a few patients deserved more weight. Maybe two patient groups were read as one because their language looked similar. Maybe a more representative quotation would have carried a finding better than a striking one. Observations like these are specific and actionable. They point to exactly where the method can be sharpened.
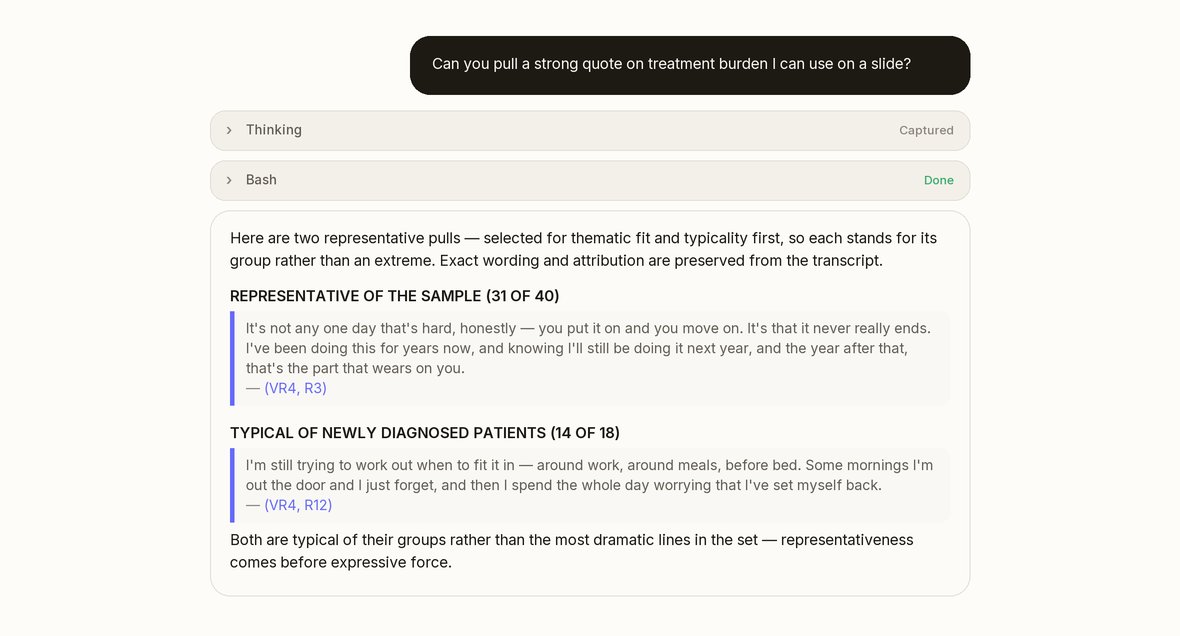
Verbatim selection in practice: representative quotes chosen for typicality (not dramatic effect).
So, that's what we do. We sharpen the workflow. An expert observation becomes a lasting refinement to the workflow, not a one-off edit to a single answer. The judgment our researchers bring gets built back into the workflow where it benefits every project that uses it in the future. Take the treatment-burden comparison from our last post. An early version of a workflow might lean on one especially vivid quote to carry the ‘newly diagnosed’ group, when a quieter response actually represented it better. An expert flags it; we adjust how that workflow weighs representativeness against expressive force; and from then on, every project that runs it inherits the fix.
Our Experts Prove It Holds Up
A refinement isn't finished the moment one example looks better. Our experts review the updated workflow the same careful way they reviewed the original, checking that it fixed what we set out to fix, that it kept the strengths it already had, and that it behaves consistently rather than trading one problem for another. Improvement is cumulative, and every change has to earn its place before it reaches you.
The same discipline is how we handle the steady arrival of new AI models. Newer isn't automatically better for a given research task, so we evaluate a promising model against the work our experts understand before we adopt it, and we bring it into our platform only once it genuinely improves the research behavior you rely on. The pace of AI works for you, guided by our experts who know what good analysis of voice data looks like. So, the version number on a language model matters far less than the judgment our experts apply before adopting it.
We’re confident putting this information out there publicly because it’s a hard loop to copy: real research observations, expert judgment, a lasting change to the method, and a careful check that it holds. Each turn captures a little more of inVibe's expertise applied to providing you with an AI whose outputs are reliable and trustworthy.
That’s the whole series in one line. Expertise designs the workflow, testing earns your trust in it, continued access puts it to work across the partnership, and our experts keep making it better.
This is what you should expect from your partners when AI is done right, and it's what we'd love to show you on your next project.
Want to Learn More?
Interested in learning how inVibe combines expert-designed AI workflows with the judgment of experienced researchers? Contact our team to explore how our Agent can extend the value of your next inVibe project.